Open source durable execution
Build forthe lonngrun.
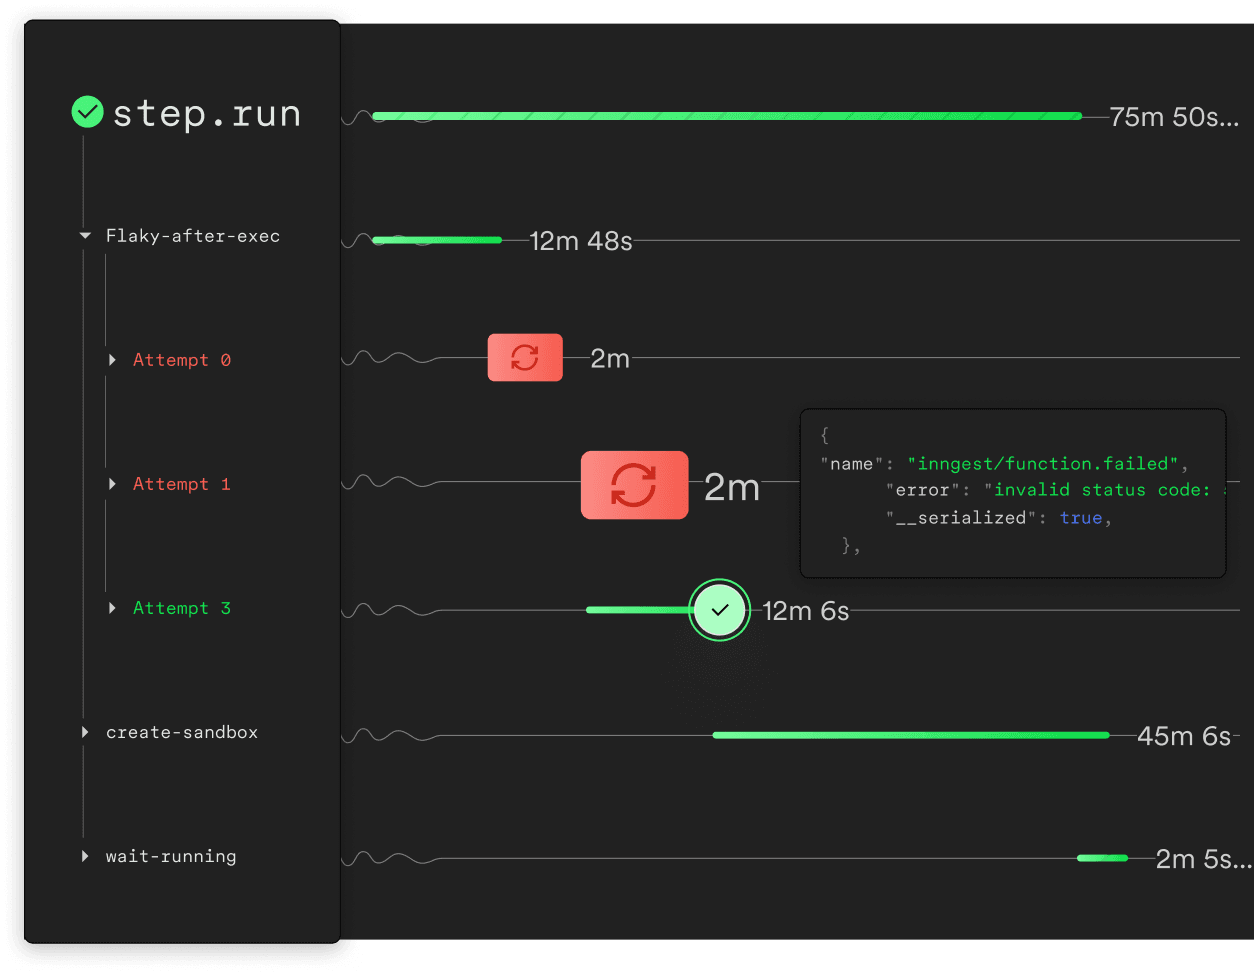
If your code runs for minutes or days, it won't run straight through. Wrap functions in steps that automatically retry, pause, and fan out. Scale instantly, without thinking about infra.






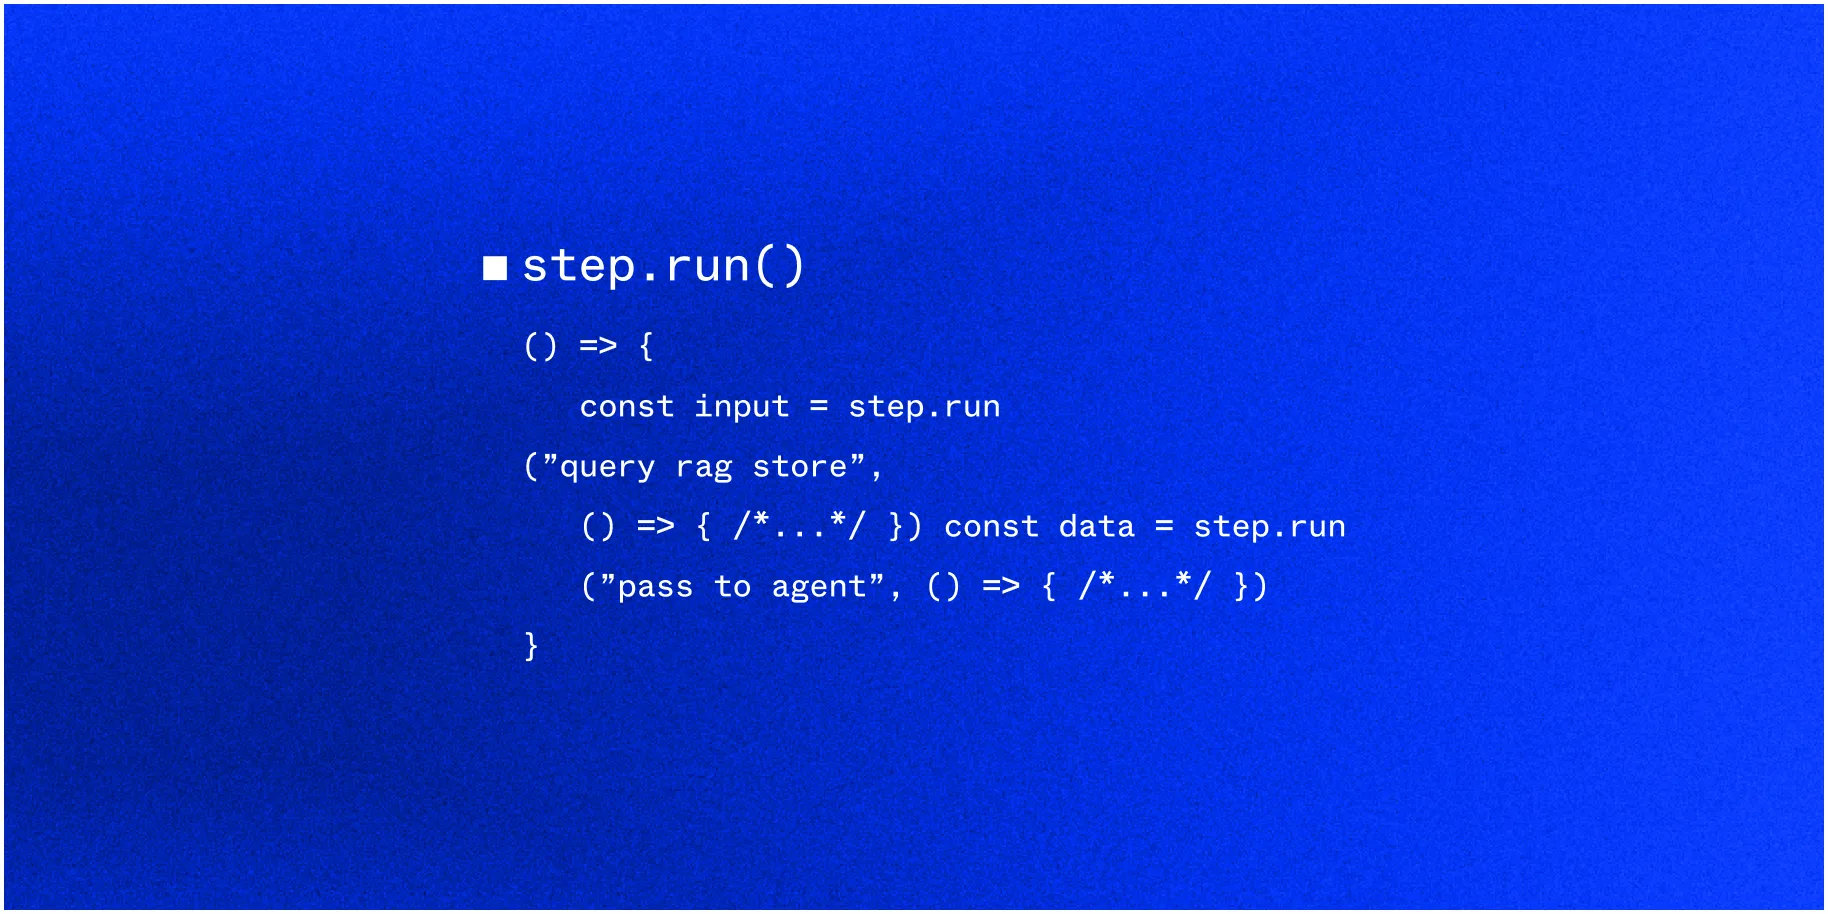
Durable doesn't have to be hard.
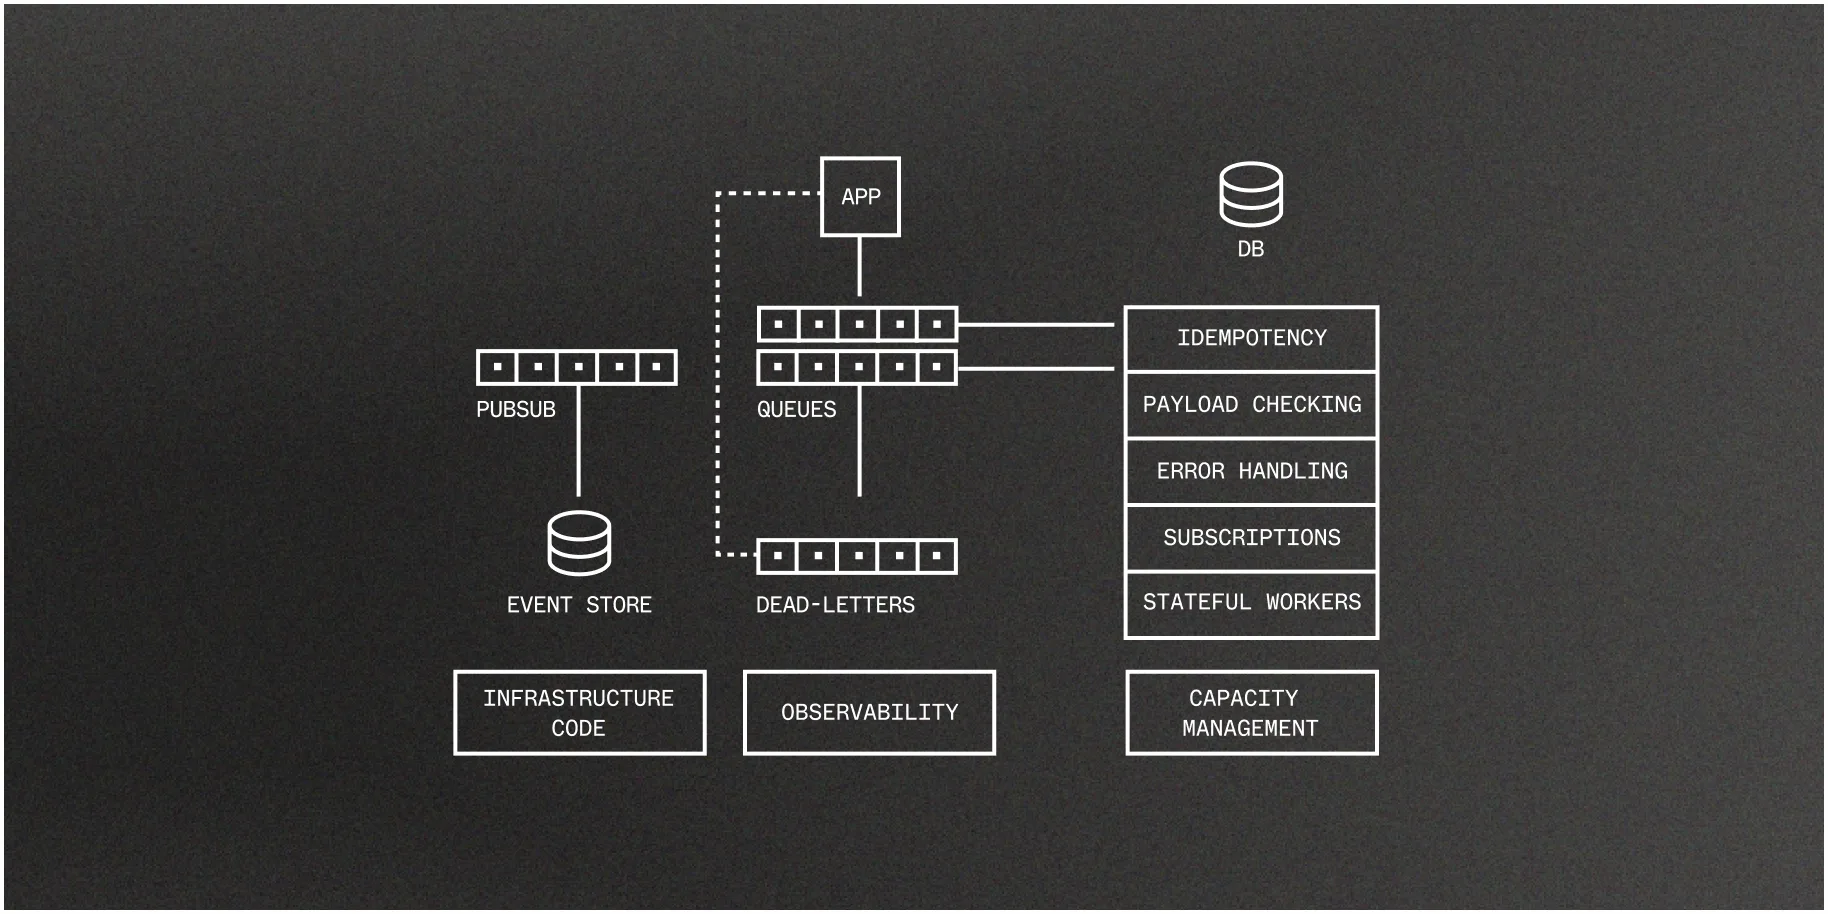
Orchestrating lonng-running code is tough. But you don't need to wrangle a bunch of extra infrastructure to do it. The Inngest SDK is the fastest way to make any code durable and observable by default.
Because one request is never the finish line.
However it's written, wherever it runs, Inngest makes lonng running jobs (and short sprints), unbreakable.
Start building.
Pick a quickstart
 Next.js
 Node.js
 Python
Learn more
What does it mean to be long running?
If you’re building anything that needs to stop, start, or retry based on an event, you’re building a long-running workflow. Find best practices here:
Long running everything
Long-running work is anything that can’t finish in a single request. Learn how to ensure it stays durable.
Read the blogRun long jobs on serverless hosts
Keep agents and multi-step jobs running past your host’s request limit, without moving off serverless.
Read the docsProcess large datasets without starting over
Run jobs that take hours or days, survive crashes and deploys, and never redo finished work.
Read the docs
Keep building.
Explore the technical ideas behind lonng-running agents and workflows.